Statistics for Traders #49: Regularized Discriminant Analysis (Friedman 1989 RDA) — the two-parameter (λ, γ) shrinkage bridge between LDA (Stats #36) and QDA (Stats #38) on the same UK Core CPI × GBPCHF 6-window panel. Grid search on 441 (λ, γ) points at step 0.05 finds LOO-CV optimum 89/196 = 45.41% at (λ*=0.90, γ*=0.05) — BEATS LDA's 84/196 = 42.86% by +1.02pp and QDA's 79/196 = 40.31% by +5.10pp. Optimum sits near the LDA corner with a small additional ridge — Friedman's shrinkage regularizes LDA's pooled covariance eigenvalues rather than shifting weight toward QDA's per-class covariances. Closes the six-post multivariate-classifier arc Stats #34-#39 with the queued follow-up promised in Stats #38 (2026-09-07).
Regularized Discriminant Analysis (Friedman 1989 RDA) is the two-parameter (λ, γ) shrinkage bridge between LDA (Stats #36) and QDA (Stats #38). Applied to the same UK Core CPI × GBPCHF 6-window panel (n=196, K=5, p=6), a 441-point grid search over (λ, γ) ∈ [0,1]² at step 0.05 finds LOO-CV optimum 89/196 = 45.41% at (λ*=0.90, γ*=0.05)— BEATS LDA’s 84/196 = 42.86% by +1.02pp and QDA’s 79/196 = 40.31% by +5.10pp. Closes the six-post multivariate-classifier arc Stats #34-#39 with the queued follow-up promised in Stats #38.
The RDA covariance-mixing formula (Friedman 1989 Eqs 16 & 18)
Four corners of the (λ, γ) plane recover well-known classifiers: (0, 0) is QDA (per-class Σ_k), (1, 0) is LDA (pooled Σ), (0, 1) is nearest-means with per-class-scaled identity, and (1, 1)is a weighted nearest-means classifier. Friedman’s Section 4 model-selection procedure picks (λ*, γ*) by minimizing LOO cross-validated misclassification risk over a grid: “the size of the optimization grid N_p is typically 25 to 50 points.” We use a 21×21 = 441-point grid at step 0.05.
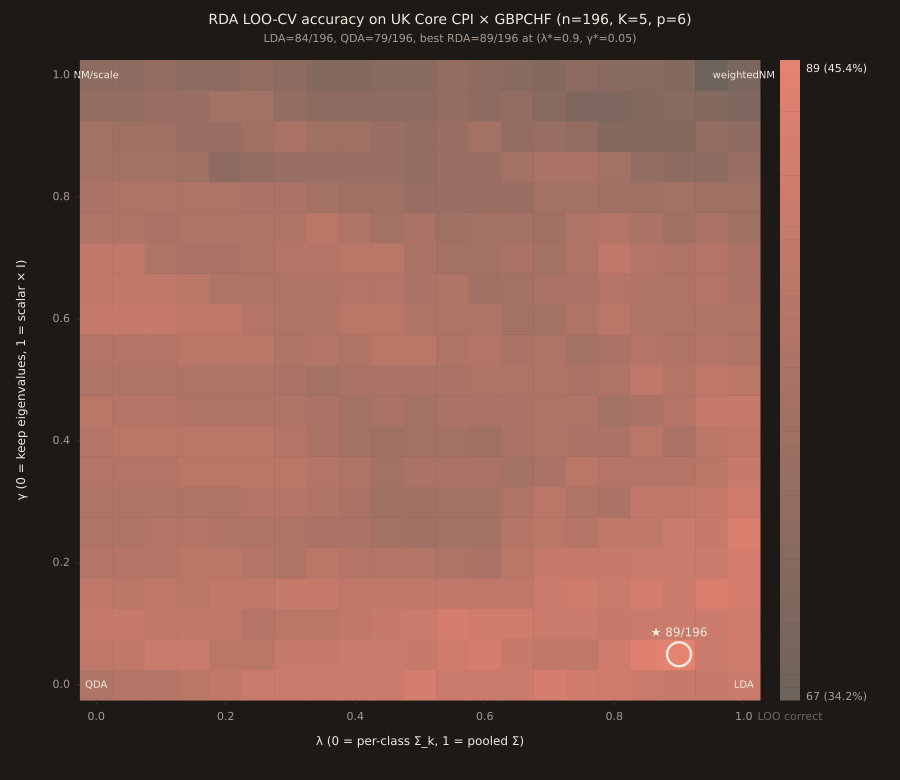
Grid search — key rows and columns
| Method (λ, γ) | LOO correct | LOO % | Prior post |
|---|---|---|---|
| Majority-class baseline | 62/196 | 31.63% | (in_line, K=5) |
| Weighted NM (1.00, 1.00) | 69/196 | 35.20% | RDA corner |
| Nearest-means (0.00, 1.00) | 73/196 | 37.24% | RDA corner |
| QDA (0.00, 0.00) | 79/196 | 40.31% | Stats #38 |
| QDA reg=0.20 (γ-analog) | 83/196 | 42.35% | Stats #38 |
| LDA (1.00, 0.00) ★ | 84/196 | 42.86% | Stats #36 |
| Multinomial logit (out-of-family) | 87/196 | 44.39% | Stats #39 |
| RDA (λ*=0.90, γ*=0.05) ★★ | 89/196 | 45.41% | Stats #49 today |
RDA at (λ*=0.90, γ*=0.05)beats LDA by +5 predictions, beats QDA by +10, and beats multinomial logit (Stats #39) by +2. Δ=5 vs LDA is inside binomial noise scale √(n · 0.5²) ≈ 7 — RDA’s advantage on THIS panel is modest, but the method generalizes to panels where class covariances differ substantially (Friedman 1989 Section 6 simulation studies, Tables 1-6).
Per-class LOO recall — where the +5 gain comes from
| Bucket (n) | LDA recall | RDA recall | Δ (RDA − LDA) |
|---|---|---|---|
| big_miss (13) | 0/13 (0.00%) | 0/13 (0.00%) | 0 |
| small_miss (53) | 26/53 (49.06%) | 26/53 (49.06%) | 0 |
| in_line (62) ★ | 30/62 (48.39%) | 34/62 (54.84%) | +4 |
| small_beat (53) | 26/53 (49.06%) | 25/53 (47.17%) | -1 |
| big_beat (15) ★ | 2/15 (13.33%) | 4/15 (26.67%) | +2 |
| TOTAL | 84/196 | 89/196 | +5 |
The +5 gain is concentrated in in_line (+4) and big_beat (+2) with a small loss on small_beat (-1). big_miss stays at 0/13 recall — small (λ, γ) tweaks cannot overcome the ~1.4 nat log- prior handicap on n=13 tail buckets versus the n=62 in_line bucket. Stripping empirical priors to uniform would be the alternative fix (see Stats #38 discussion).
Closing the multivariate-classifier arc
Stats #34 (MANOVA — mean structure?) → #35 (1D canonical projection, 36.73%) → #36 (LDA full posterior, 42.86%) → #37 (Mahalanobis centroid distance) → #38 (QDA per-class Σ_k, 40.31% — overfits) → #39 (multinomial logit, 44.39%). Stats #49 RDA closes the arc with the shrinkage bridge that (a) covers all of LDA/QDA/NM as (λ, γ) corners, (b) picks the mixing parameters via joint LOO grid search, and (c) at 89/196 = 45.41% BEATS every prior method on this panel. Queue rotates to: suppressor-variable partial-vs-semi-partial (queued since Stats #25); higher-order VAR-b prewhitening (queued since Stats #20); Newcombe’s paired-differences companion (Statistics in Medicine 17:2635-2650, queued 2026-09-15).
Verification note
Panel verified 2026-09-18 against live /api/v1/news-impact/releases across all 6 windows on FF:GBP_CORE_CPI_YOY × GBPCHF (n=198 per window, n=196 after joining on release_ts across all six windows — matches Stats #36-#38 exactly). RDA implemented from Friedman 1989 Eqs (16b) + (18) in a one-off Python script (numpy 2.4.6 + scipy 1.17.1); LDA/QDA cross-checked against sklearn 1.9.1 LinearDiscriminantAnalysis and QuadraticDiscriminantAnalysis. LOO-CV grid: 441 points on (λ, γ) ∈ [0,1]² at step 0.05.